TCB Infotech | Expert Odoo & ERPNext Implementation Partner
Schedule Call With Us
LLM Engineers

Hire Dedicated LLM Engineers

Add a vetted LLM engineer to fine-tune, serve and optimize the model layer for latency, cost and accuracy at your actual usage volume.

50+ ERP and software projects. Zero failed projects since 2021.

LLM Serving Layers
🧠
Base model
Selected to fit the task and budget
⚙
Fine-tune / adapter
Tuned on your domain data
📊
Serving layer
Latency and cost optimized
🔗
API endpoint
Connected to your application
1-2 wk
Typical shortlist time
100%
Screened on serving and cost work
Flexible
Full time, part time or project
Free
Replacement if not a fit
Why It Matters

The model is the easy part. Running it well is not

Calling a model API is simple. Keeping latency low and cost predictable at real usage volume is where most teams get stuck.

Right-Sized, Not Default

The model that fits the task, not the biggest one available

A larger model is not always a better choice. A dedicated LLM engineer matches the model to the task, fine-tunes it on your domain data where it helps, and avoids paying for capability you do not need.

  • Model choice matched to the task and budget.
  • Fine-tuning where it actually improves results.
  • No lock-in to a single vendor or model.
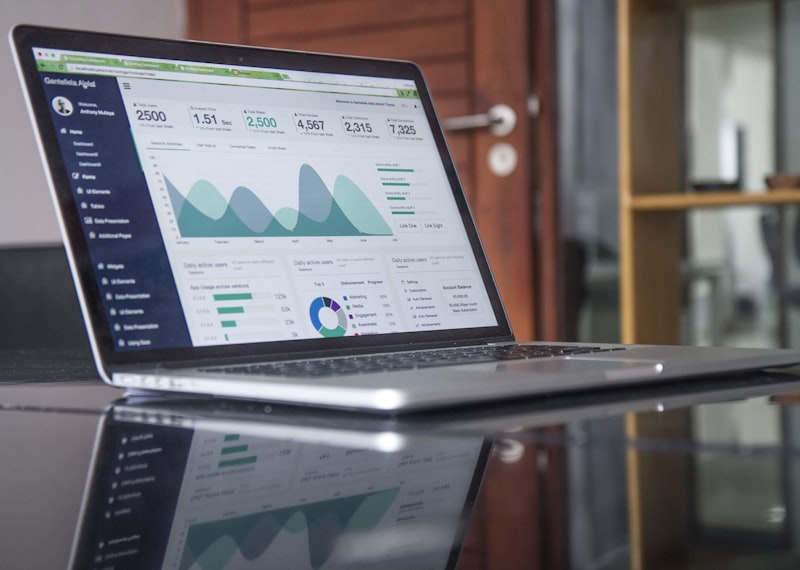
An engineer configuring a model serving layer
Latency and Cost Under Control

A serving layer built for your real traffic

Caching, batching and concurrency settings make the difference between a feature that feels instant and one that times out under load. A dedicated engineer tunes this against your actual usage, not a demo.

  • Serving tuned for your real traffic patterns.
  • Caching to cut repeated inference cost.
  • Cost tracked and kept predictable.
A dashboard showing model serving performance
What the Serving Layer Looks Like

The same four layers, tuned to your workload

Whether the workload is a chat feature or a batch job, it runs through this same stack.

Example: A High-Volume Support Assistant
🧠
Right-sized base model
Chosen for cost at scale
⚙
Domain fine-tune
Tuned on past support tickets
📊
Cached serving layer
Repeated queries answered instantly
How Hiring Works

From requirements to a working engineer in about two weeks

1
Share requirements
Tell us your workload, current latency or cost pain points, and your usage volume.
2
Shortlist
We match engineers by serving and fine-tuning experience and send you 2 to 3 profiles.
3
Interview
You interview the shortlist directly and pick the engineer who fits your workload and team.
4
Onboard
The engineer reviews your current setup and starts tuning the serving layer in the first week.
5
Scale as needed
Add a second engineer or move to part time once performance and cost are stable.
What's Included

Everything you need to run the engagement smoothly

🎯

Dedicated to your project

The engineer works only on your account, not split across other clients' workloads.

💬

Direct communication

You talk to the engineer directly on your tools, with no account manager relay in between.

📅

Flexible contracts

Full time, part time, or a fixed scope of work. Scale up or down with notice, not a long lock-in.

✅

Latency and cost reviews

Serving performance and cost reviewed against agreed targets, not left unmonitored.

🌐

Timezone overlap

Working hours arranged to overlap with your team for stand-ups and reviews.

🔐

Replacement guarantee

If the engineer is not the right fit, we replace them at no extra cost during the engagement.

What Changes

What a dedicated LLM engineer changes for your workload

Lower
Inference cost per request
Faster
Response times under load
Right-sized
Model for the actual task
Predictable
Cost as usage scales
Model-agnostic
No single-vendor lock-in
Lower
Cost than a full-time direct hire
Why Us

Why teams hire LLM engineers through TCB Infotech

1
We run model workloads ourselves
We serve language models in production for clients, so our engineers are tested on real latency and cost pressure, not trivia.
2
Fast, honest shortlisting
You see 2 to 3 profiles, not a stack of resumes, and we tell you plainly if a fit is not right.
3
Direct access, no relay
You manage the engineer's day to day work directly, on your tools and your process.
4
Setup you can keep
Serving configuration and fine-tuning work are documented and handed over cleanly if the engagement ends.
5
No long lock-in
Scale the engagement up or down with notice, based on your actual workload.
6
Proven delivery
50+ ERP and software projects, with zero failed projects since 2021.
FAQ

Hiring LLM engineers, answered

What does a dedicated LLM engineer do?
They select the model that fits your task and budget, fine-tune it on your domain data where useful, and build the serving layer that keeps latency and cost under control at your actual usage volume.
Does the engineer lock us into one model?
No. The approach is model-agnostic. The engineer chooses and configures whichever model fits your data, latency and budget, and can swap it later if a better fit becomes available.
How is this different from a generative AI engineer?
An LLM engineer focuses on the model layer itself: fine-tuning, serving, latency and cost. A generative AI engineer focuses on the pipeline around a content generation feature. If your need is a content pipeline rather than model infrastructure, see our Generative AI Engineers.
Can you reduce our current inference cost?
Often, yes. Common levers include right-sizing the model for the task, caching repeated requests, and tuning batch and concurrency settings on the serving layer.
What is the engagement model?
You can hire full time, part time, or for a fixed project. Contracts scale up or down as your model workload changes, with no long lock-in period.
What if the engineer is not the right fit?
We replace the engineer at no extra cost during the engagement, and hand over the serving setup and fine-tuning work to the new engineer.

Hire a Dedicated LLM Engineer

Book a free consultation. Tell us about your workload, and we will shortlist engineers who fit your latency, cost and team.

Book a Free Consultation →

No commitment. See a shortlist before you decide.