TCB Infotech | Expert Odoo & ERPNext Implementation Partner
Stop Retyping Documents Into Your Systems by Hand
Every invoice, form, contract and application that arrives as a PDF or a scan usually ends up retyped into an ERP field by field. Document AI reads the document, pulls out exactly the fields you need, shows the source next to each value so a person can confirm it in seconds, and posts the confirmed data directly into your system.
50+ ERP and software projects. Zero failed projects since 2021.
The document was already digital, the retyping wasn't
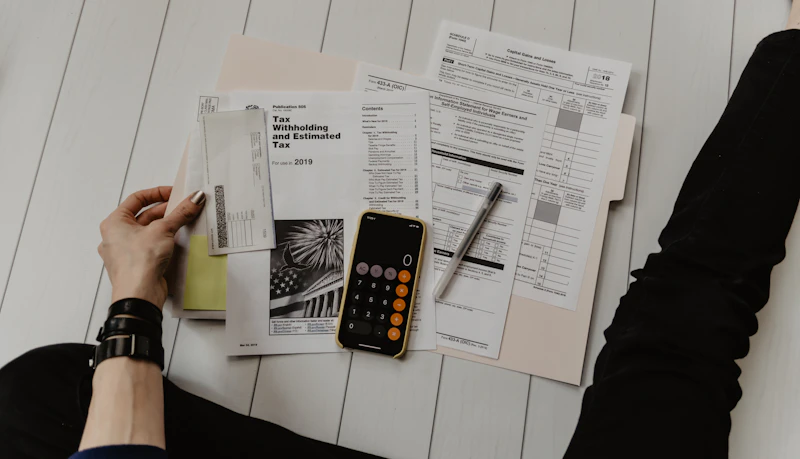
A PDF invoice already contains every field your ERP needs. Someone still opens it and types the numbers in twice.
Handles the messy formats that actually show up
Real documents are not clean templates. A scanned invoice from one supplier and a native PDF from another look nothing alike, yet both need the same fields pulled out. The extraction is built and tested on your own real document mix, not a tidy sample.
- Scanned images, photos and native PDFs all handled.
- Tested against your own real document variety.
- Layout differences between senders handled directly.
Confirm in seconds, not re-read from scratch
Every extracted field is shown against the exact spot in the source document, so confirming it is a glance, not a re-read. Low-confidence fields are flagged clearly, so a person's attention goes to the handful of values that actually need checking.
- Extracted value linked to its exact source location.
- Low-confidence fields flagged for a closer look.
- High-confidence fields ready to post without delay.

What a processed document looks like
The document, the fields pulled from it, and the confidence flag before anything is posted.
From a document arriving to data posted in your system
The documents most companies process by hand
We start with your highest-volume document type, then extend to the rest.
Invoices and bills
Vendor invoices in any layout, with line items, taxes and totals extracted for posting.
Purchase and sales orders
Order documents from customers or suppliers, extracted directly into your order system.
Contracts and agreements
Key dates, values and clauses pulled from contracts for tracking and compliance.
Applications and forms
Job applications, credit applications or onboarding forms extracted into your workflow.
Shipping and customs documents
Bills of lading, packing lists and customs paperwork read for the fields logistics needs.
Compliance certificates
Certifications and licenses checked for validity dates and required details.
What document AI changes
Why teams choose TCB Infotech for document AI
Document AI questions
What is document AI?
What document formats can it handle?
How accurate is the extraction?
Does it post directly into our ERP?
Can we see what was extracted from where?
How long does a first extraction workflow take to build?
The data was never missing, it was just locked in a PDF
Every document your business processes already contains the fields your systems need. The only step that was ever missing was a reliable way to pull them out without a person retyping every one.
Document AI fills exactly that gap: it reads the document, extracts the fields, shows its confidence, and leaves the final check to a person on anything uncertain. The document does the same job it always did, just without the retyping.
Stop Retyping Your Highest-Volume Document
Book a free consultation. Bring a sample of the document your team processes most, and we will show you what automated extraction would look like.
Book a Free Consultation →No commitment. A practical look at your document volume.